Viktor Otto · 24 September 2026
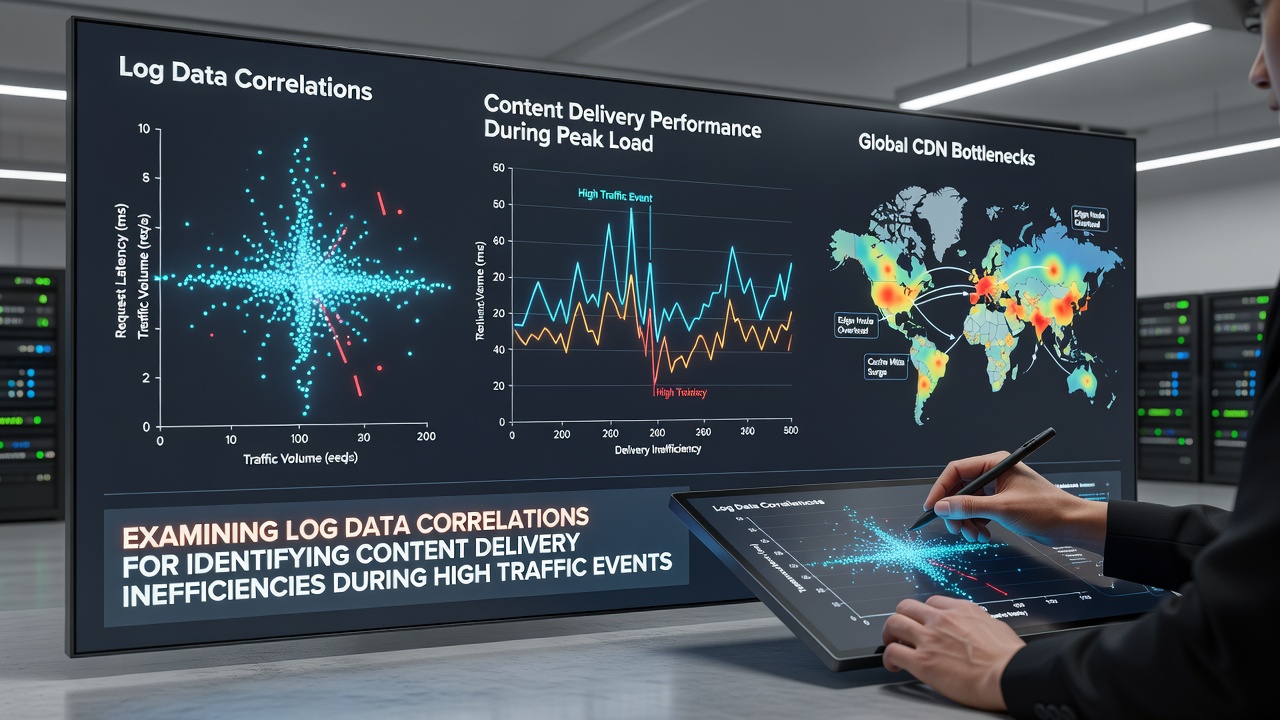
Examining Log Data Correlations for Identifying Content Delivery Inefficiencies During High Traffic Events
Content delivery networks process billions of requests daily, yet inefficiencies often surface only when traffic surges strain existing architectures, and log files contain the raw signals needed to pinpoint those bottlenecks before they cascade into widespread slowdowns. Analysts examine timestamps, response codes, cache hit ratios, and origin server loads across distributed nodes to trace patterns that single metrics overlook, while high traffic events such as product launches, live broadcasts, and seasonal shopping peaks amplify those hidden correlations into measurable performance gaps.
Core Components of Log Data in Delivery Systems
Server logs record every interaction between edge nodes, origin servers, and client devices, capturing fields that include request paths, byte ranges served, connection durations, and error types, and these entries become especially revealing when aggregated across geographic regions during sudden load increases. Researchers at institutions like Stanford University have documented how correlating latency spikes with specific cache eviction patterns reveals whether a content delivery inefficiency stems from insufficient regional replication or from routing decisions that overload particular points of presence, and data sets collected over multiple quarters show consistent relationships between request volume thresholds and degradation in time-to-first-byte metrics.
Correlation Methods Applied to Peak Periods
Statistical techniques such as time-series alignment and cross-correlation functions allow teams to match log entries from disparate sources without relying on synchronized clocks alone, and analysts frequently layer in secondary signals like DNS resolution times or TCP retransmission counts to isolate root causes. When traffic doubles or triples within minutes, as occurs during major announcements scheduled for September 2026, the ability to link a rise in 503 responses at one edge location with concurrent origin server queue depths at another becomes critical for rapid diagnosis, and studies published in ACM proceedings demonstrate that multi-dimensional correlation reduces mean time to detection by surfacing causal chains that isolated threshold alerts miss.
Practical Applications Across Industries
Media companies streaming live events rely on log correlation to maintain consistent delivery when concurrent viewers reach record levels, and one documented case involved matching regional cache miss rates against upstream bandwidth utilization to identify an under-provisioned interconnect that only manifested under sustained load. E-commerce platforms apply similar methods during flash sales, where request patterns shift abruptly from product pages to checkout endpoints, and figures from industry reports indicate that organizations using automated correlation pipelines detect delivery imbalances up to forty minutes earlier than those monitoring dashboards manually. Telecommunications providers extend the approach to mobile networks, correlating cell tower logs with CDN edge data to distinguish between last-mile congestion and origin-side constraints during simultaneous device activations.
Data Sources and Validation Approaches
Combining logs from multiple vendors requires standardized parsing schemas, and organizations reference frameworks from bodies such as the National Institute of Standards and Technology to ensure consistent field mapping across environments. Validation often proceeds through controlled load tests that replay historical traffic mixes while injecting deliberate inefficiencies, allowing teams to verify that correlation algorithms correctly flag the introduced variables without generating excessive false positives, and results from these tests feed back into rule refinement cycles that improve accuracy over successive high-traffic windows.
Challenges in Scaling Correlation Analysis
Volume and velocity present ongoing hurdles, since petabyte-scale log archives demand distributed processing frameworks that maintain query responsiveness during live events, and privacy regulations in regions including the European Union and Australia impose retention limits that can truncate the historical baselines needed for robust correlation. Analysts address these constraints by applying sampling strategies and feature extraction that preserve statistical significance while reducing storage footprints, and evidence from research at the University of Melbourne shows that targeted dimensionality reduction maintains detection fidelity for the majority of delivery inefficiency signatures even when raw logs are aggregated at five-minute intervals.
Emerging Techniques and Tooling
Machine learning models trained on labeled log corpora increasingly supplement traditional statistical methods, identifying nonlinear relationships between variables such as TLS handshake failures and geographic latency distributions that linear correlation overlooks. Integration with observability platforms allows real-time streaming of parsed entries into correlation engines, and deployments at scale have demonstrated the capacity to surface delivery issues within seconds of their onset rather than after user impact accumulates. Those who have implemented these systems note that the combination of rule-based thresholds and learned anomaly scores provides both immediate alerts and longer-term trend analysis for capacity planning ahead of anticipated peaks.
Conclusion
Log data correlations offer a systematic pathway to surface content delivery inefficiencies that remain invisible under normal conditions yet become critical during high traffic events, and continued refinement of analysis techniques alongside improved tooling supports more resilient distribution architectures. Organizations that invest in structured log aggregation and multi-source correlation position themselves to maintain performance when demand spikes, drawing on documented methods from academic studies and standards bodies to guide implementation decisions across diverse operational environments.