Viktor Otto · 10 September 2026
Uncovering Hidden Redirect Chains Through Beampier’s Log File Analysis Features
Site administrators routinely examine server logs to identify inefficiencies that emerge after structural changes to websites, and Beampier’s log file analysis features provide structured methods for detecting hidden redirect chains that otherwise remain obscured in standard reports. These chains form when multiple HTTP redirects stack together following updates such as content migrations, URL restructuring, or platform upgrades, and they consume additional server resources while slowing page delivery. Data from web infrastructure studies indicate that each extra redirect in a chain increases latency by an average of 100 to 300 milliseconds depending on server configuration and geographic distribution of users.
Structural Changes and Emerging Log Patterns
Website reorganizations often trigger sequences of redirects that administrators track through timestamped entries in access logs, and Beampier processes these entries to surface repeated patterns across large datasets. Researchers at institutions such as the National Institute of Standards and Technology have documented how even minor directory shifts create cascading redirects that compound over months if not isolated early. Log analysis reveals clusters of 301 and 302 status codes pointing to intermediate locations before final resource delivery, and these clusters appear most frequently in sites that underwent CMS migrations or domain consolidations within the prior 12 months.
Administrators who review daily log aggregates notice that certain user agents trigger longer chains than others, particularly when crawlers encounter legacy internal links that point to deprecated paths. Beampier’s filtering capabilities allow segmentation of log data by user agent, request path, and response code sequence, which isolates the exact points where chains originate. This segmentation proves especially useful after large-scale content updates because it highlights redirect loops that only surface under specific traffic conditions rather than in every request.
Beampier Log Parsing Capabilities
The platform ingests raw server logs in common formats including Apache combined and Nginx extended, then applies pattern-matching algorithms to reconstruct full redirect sequences from individual line entries. Observers note that the tool flags chains exceeding two hops automatically, while providing drill-down views that display the complete path from initial request to final resource. In September 2026, planned enhancements to Beampier’s export functions will allow direct integration with external monitoring dashboards used by enterprise teams managing multi-region deployments.
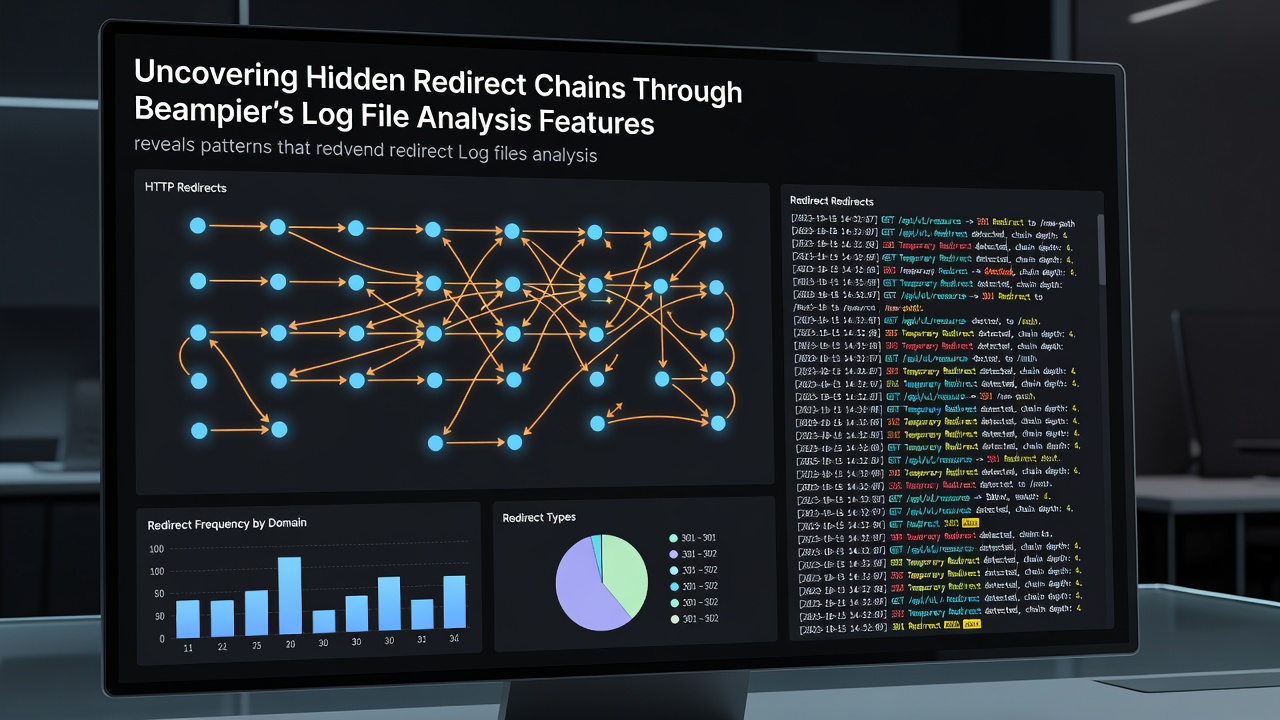
Those who manage high-traffic properties report that the analysis surface previously undetected chains caused by plugin conflicts or misconfigured rewrite rules, and the resulting reports include frequency counts that help prioritize remediation efforts. The system correlates redirect data with response times extracted from the same log lines, producing visualizations that map chain length against average load duration for each affected URL.
Tracking Inefficiencies Across Log Datasets
Server logs accumulate entries that reflect both successful and failed redirect attempts, and Beampier organizes these into time-series views that show how inefficiency metrics evolve after structural modifications. A study conducted by the University of Melbourne’s computing research group examined logs from 47 mid-sized sites and found that post-migration redirect chains accounted for a measurable increase in cumulative server CPU time, with some chains persisting undetected for over 90 days. Administrators apply Beampier’s query builder to isolate entries where the referer field indicates internal navigation, thereby distinguishing between user-facing chains and those encountered only by automated systems.
Cross-referencing occurs when the tool matches log entries against sitemap files or crawl data supplied by the user, which reveals discrepancies between declared site structure and actual redirect behavior recorded in logs. This comparison helps surface chains that result from outdated canonical tags or stale XML sitemaps that continue to reference legacy paths long after content relocation.
Practical Applications in Ongoing Site Maintenance
Teams responsible for large content libraries use the analysis output to generate remediation lists that target the longest or most frequent chains first, and they schedule log re-analysis after each fix batch to confirm chain elimination. The process relies on the same log sources that already exist within standard server configurations, so no additional data collection infrastructure is required beyond initial Beampier setup. Patterns identified in one domain often repeat across related properties managed by the same organization, allowing administrators to apply consistent cleanup rules site-wide.
Conclusion
Beampier’s log file analysis features supply site administrators with repeatable methods for uncovering hidden redirect chains that develop after structural website changes, and the resulting data supports targeted corrections that restore efficient request handling. Continued monitoring of server logs through these tools maintains visibility into redirect behavior as sites evolve over time.